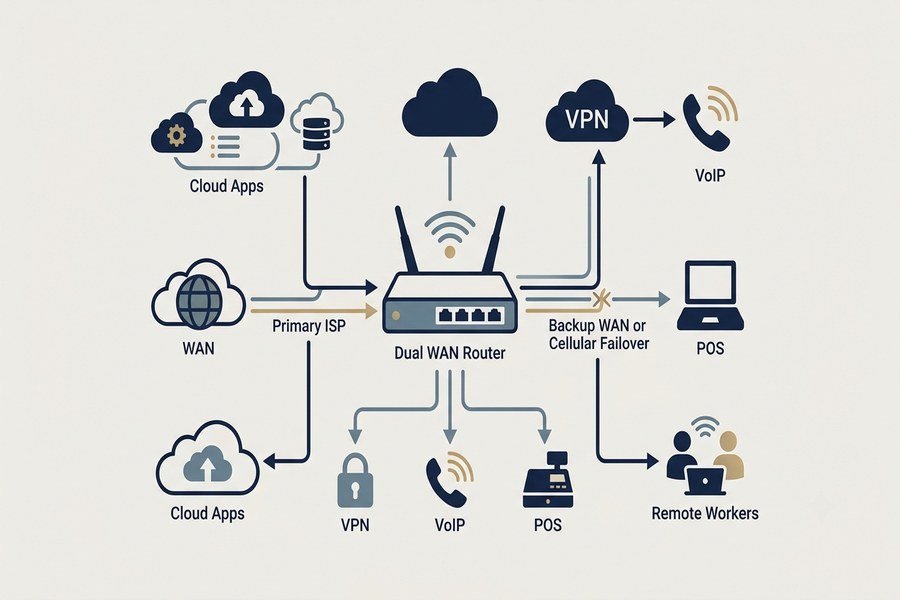
If your business cannot afford a dead VPN tunnel, a branch-office outage, or a frozen payment terminal during peak hours, you are not really asking for “better WiFi.” You are asking for a network that stays available when a line fails, a device crashes, or traffic suddenly spikes. That is exactly why so many IT buyers search for high availability enterprise networking instead of generic connectivity advice.
A high availability enterprise network is built to keep business services running even when something goes wrong. It uses redundant enterprise router architecture, failover logic, resilient WAN design, and carefully planned hardware paths so users still reach cloud apps, ERP systems, cameras, voice platforms, and branch resources without a hard stop.
If you are comparing solutions for a regional office in Poland, a healthcare site in Southeast Asia, a logistics branch in the Middle East, or a multi-branch retail rollout in Latin America, the real question is not “what is availability?” The real question is what kind of redundancy, dual uplink deployment, and enterprise failover system you need to protect nonstop business connectivity without overbuilding the network.

- 1. What does high availability really mean in an enterprise network?
- 2. Why is high availability different from ordinary network stability?
- 3. What components make up a high availability enterprise network?
- 4. How does enterprise failover actually work in real operations?
- 5. Where is high availability most important?
- 6. How should businesses design for redundancy without overspending?
- 7. What are common mistakes in high uptime infrastructure projects?
- 8. How do you evaluate a high availability network solution?
- Conclusion
- FAQ
1. What does high availability really mean in an enterprise network?
1.1 It means the business keeps operating when a single point fails
High availability does not mean a network is perfect. It means the network is engineered so one failure does not immediately stop business operations. If one ISP drops, one uplink is cut, one switch dies, or one router process hangs, the rest of the design still carries critical services forward.
1.2 Availability is measured in service continuity, not just device power-on time
Many teams say a site is “up” because the router still has lights on. That is not a useful business definition. In a mission critical networking environment, availability means users can still authenticate, reach cloud systems, complete transactions, join voice calls, and access core applications with tolerable degradation instead of a total stop.
1.3 High availability is about architecture, not one premium box
Buying an expensive gateway alone does not create a resilient WAN design. Real availability comes from layered planning: dual WAN, smart routing policy, redundant power if needed, segmented traffic, backup access paths, and failover testing. This is why a dual WAN router for business continuity matters more than a single high-spec router with no backup path behind it.
2. Why is high availability different from ordinary network stability?
2.1 Stable is good on normal days; high availability is built for bad days
A stable network performs well under expected conditions. A high availability enterprise network performs acceptably even during failure events. That difference matters in finance, healthcare, warehousing, branch retail, and service operations where a thirty-minute outage has a direct revenue or compliance cost.
2.2 Availability planning assumes faults will happen
Ordinary small-office networking often assumes the internet line, router, and access layer will mostly behave. Enterprise redundancy architecture assumes the opposite: links flap, firmware bugs happen, carriers fail, fiber gets damaged, and local power conditions can become ugly. The design starts from failure tolerance instead of optimistic hope.
2.3 The recovery path is part of the design, not an afterthought
In ordinary networks, recovery often depends on a technician noticing the outage, logging in remotely if possible, and making manual changes. In a true enterprise failover system, recovery paths are already defined. Traffic can shift from primary broadband to LTE, from one ISP to another, or from one route policy to a backup tunnel with minimal interruption.
That distinction becomes obvious in real deployments. A branch in Warsaw can survive a local ISP interruption if its WAN edge was designed for automatic failover, but the same branch may go completely dark if its “stable” network depended on a single cable and one default route. This is also why many industrial operators look at redundant industrial networking for 24/7 factory uptime instead of treating uptime as a simple bandwidth question.

3. What components make up a high availability enterprise network?
3.1 Redundant WAN links are usually the first requirement
The most visible component is dual uplink deployment. Two internet lines from the same carrier are better than one, but two different carriers are usually better still. If one provider has a regional issue, your backup remains meaningful. In many enterprise branch scenarios, this is the fastest way to improve uptime, especially when teams compare gigabit WiFi 6 router solutions that can support stable branch connectivity without pushing the budget into unnecessary complexity.
3.2 Intelligent routing and failover policies decide what happens next
Redundancy without policy is messy. The router needs rules for health checks, route preference, session persistence, VPN failover, and which applications get priority during degraded operation. A practical network redundancy architecture often includes application-aware traffic handling so voice, ERP, and payment flows survive before non-essential traffic does. In some upgrades, that policy layer is paired with WiFi 6 router platforms that can support segmented branch traffic and cleaner failover behavior.
3.3 Resilient LAN and access design prevents edge failures from spreading
WAN resilience is only part of the story. A mission critical networking environment also needs sane VLAN design, loop prevention, power planning for switches and APs, and enough segmentation to stop one local issue from cascading into a full-site outage. In hospitals and care facilities, this becomes especially important because user traffic, medical terminals, and operational devices cannot all share the same risk domain, which is why high-reliability branch design overlaps with guidance such as why healthcare networks need high reliability routers.
4. How does enterprise failover actually work in real operations?
4.1 The network monitors path health continuously
Failover should not rely on a human refreshing a dashboard. A router or controller checks link status, gateway reachability, DNS resolution, latency, or other health signals. If the primary path becomes unreliable, the system marks it as degraded or unavailable.
4.2 Traffic shifts based on pre-defined priorities
When failover triggers, the design may move all traffic to a backup uplink, or it may move only essential services first. A strong enterprise failover system avoids chaos by clearly defining what happens during the first seconds of an outage and what stays online under limited bandwidth conditions. That is also why some buyers shortlist WiFi 7 business router options when they expect denser client loads and longer-term branch growth.
4.3 Recovery must be clean when the main path returns
Failover is only half the job. Failback matters too. If the primary link comes back, the network should restore normal routing without killing user sessions unnecessarily or bouncing tunnels in a way that creates a second outage. This is where high uptime infrastructure projects often succeed or fail in practice.
Consider a multi-branch distributor using ERP, VoIP, and cloud inventory tools. If the main fiber circuit fails during a sales surge, a backup 5G or broadband path may keep orders flowing. But if the failback logic is poorly tuned, staff can still get kicked out of active systems the moment the primary carrier recovers. That is not resilient WAN design. That is just outage ping-pong.

5. Where is high availability most important?
5.1 Multi-branch operations need consistency across locations
Retail chains, clinics, service networks, and distributed offices often depend on identical access to cloud platforms, POS systems, and centralized administration. If one branch loses connectivity, the business impact can be immediate. This is why buyers often pair resilient WAN design with planning for networking solutions for multi-branch enterprises rather than evaluating each site in isolation.
5.2 Factories, hospitals, and service environments cannot wait for manual recovery
In a normal office, a ten-minute interruption is annoying. In manufacturing, a stop can delay output and labor. In healthcare, a stop can delay access to records, imaging systems, or bedside workflows. In field service and logistics, it can break scanning, dispatch, or remote reporting. High availability matters most where downtime has operational consequences beyond inconvenience.
5.3 Any business with customer-facing transactions should care
Hospitality, retail, financial service points, and distribution counters all rely on nonstop business connectivity. If the network fails during a payment, onboarding, or order-confirmation workflow, the issue is visible to the customer immediately. That makes availability part of brand reliability, not just infrastructure engineering. For customer-facing branches, practical hardware evaluation often includes gigabit business router choices that balance failover readiness, throughput, and daily operational simplicity.
6. How should businesses design for redundancy without overspending?
6.1 Protect the true single points of failure first
Not every site needs full datacenter-style HA. Most businesses should start by finding the single points that create the biggest downtime risk: one ISP, one core router, one uplink to the branch switch, one tunnel path for all VPN traffic, or one power source for the edge stack. Fixing these can deliver a major uptime improvement without turning a mid-sized office into a science project.
6.2 Match the backup method to the business consequence
If a warehouse only needs order flow and scanner traffic protected, a dual uplink deployment with policy-based failover may be enough. If a clinic needs always-on access for records, imaging coordination, and voice services, the design may need better path diversity, stronger failover testing, and more conservative hardware choices. The right redundancy level comes from business impact, not from vendor marketing. In this stage, some IT teams compare an AX1500 WiFi 6 router or similar branch-class hardware only after they have mapped the applications that truly need protected uptime.
6.3 Use practical product selection, not theoretical perfection
Many teams overspend because they design for every imaginable disaster. A smarter approach is to build a high uptime infrastructure around realistic failure patterns. For example, one robust business router, one backup uplink, clean VPN failover, and careful segmentation can often outperform a more expensive but poorly planned stack. In medium-sized enterprise projects, buyers also look at field-proof deployments such as the Warsaw financial office tower WiFi coverage project to see how resilient business connectivity decisions play out in a real office environment.
This is also where the second placement of the COMFAST router portfolio makes sense in the article flow: once you know the real failure points, product comparison becomes more rational and less driven by spec-sheet noise.

7. What are common mistakes in high uptime infrastructure projects?
7.1 Buying redundant links without testing real failover behavior
Two links on paper do not guarantee availability. If DNS policies, VPN tunnels, health checks, or route preferences are misconfigured, the backup path may never activate properly. A lot of so-called redundant enterprise networks are only redundant in presentation slides.
7.2 Ignoring application priority during degraded conditions
When backup bandwidth is lower than the primary path, something has to give. If the network treats software updates, guest traffic, and payment traffic equally, the business still suffers. Mission critical networking requires traffic prioritization, not just failover.
7.3 Treating LAN resilience as somebody else’s problem
It is common to focus on the WAN edge and forget the local environment. Loop issues, badly placed switches, single-switch dependence, and weak power planning can still take a site offline even if the WAN layer is beautifully redundant. High availability enterprise networking is end-to-end thinking, not WAN-only thinking.
8. How do you evaluate a high availability network solution?
8.1 Ask what specific failure scenarios the design survives
A useful solution should answer clear questions. Does it survive one ISP outage? One router reboot? One tunnel drop? One branch switch uplink failure? If the answer is vague, the design is probably still immature.
8.2 Check whether failover is automatic, measurable, and testable
Buyers should ask how health checks work, how long failover usually takes, how rollback is handled, and how often the system should be tested. A real enterprise failover system should be observable and repeatable, not mystical.
8.3 Evaluate manageability across the whole business, not one site
For a single branch, a basic redundant setup may be enough. For a national rollout, the bigger question is whether policies can be standardized, monitored, and supported across dozens of locations. That is what separates a clever local fix from a scalable network redundancy architecture.
If you are comparing vendors, stop asking only about maximum throughput. Ask how the design supports mission critical networking, dual uplink deployment, resilient WAN design, and nonstop business connectivity in your exact business model. Those answers are usually far more valuable than another headline speed number.
Conclusion
A high availability enterprise network is not just a “fast network.” It is a network designed so the business can keep moving when a carrier fails, a link drops, or a device has a bad day. The core idea is simple: remove single points of failure, define smart failover behavior, protect critical applications first, and align redundancy with the real cost of downtime.
For most businesses, the smartest path is not maximum complexity. It is a practical architecture that combines redundant WAN access, clear routing and failover policy, resilient local design, and hardware that matches the operational stakes of the site. When you evaluate availability that way, you make better decisions and avoid paying for the wrong kind of “enterprise” network.
FAQ
What is the difference between network redundancy and high availability?
Network redundancy is one method used to achieve high availability. Redundancy adds backup links, paths, or devices, while high availability is the broader goal of keeping business services online despite failures.
Does every enterprise need dual uplink deployment?
No. But any site where downtime quickly affects revenue, customer service, compliance, or branch operations should seriously consider dual uplink deployment as a baseline availability measure.
Can a small or mid-sized company build a high availability enterprise network?
Yes. High availability does not have to mean a huge budget. Many SMEs improve uptime significantly by removing key single points of failure, adding one backup WAN path, and using cleaner failover policy.
Why is failback just as important as failover?
If the network returns to the primary link too aggressively or too messily, users can experience a second disruption after the first one is already over. Clean failback keeps recovery from becoming another outage.
What kind of COMFAST products are relevant for high availability business networking?
Businesses usually look at business-class routers, dual WAN capable gateways, and branch-friendly wireless routing products that fit stable uptime requirements. The right choice depends on site size, uplink model, traffic priorities, and management needs.
Need a practical high availability network design for your business?
Talk with COMFAST about branch office redundancy, dual uplink deployment, resilient WAN hardware, and enterprise router options that fit your budget and uptime target.